To build a generative AI model for image synthesis, most teams start from an open diffusion model, fine-tune it on their own images, measure the output and serve it through an API. Training a new image model from scratch is possible, but it needs millions of images and a large GPU budget.
This guide gives the steps for both paths, explains the model types (diffusion models, GANs and VAEs), and covers quality checks and safety.
Key facts
- Diffusion models power most image generators since 2022, including Stable Diffusion, DALL-E, Midjourney and Imagen.
- Fine-tuning with LoRA can teach an existing model a new style or product from a few hundred images.
- FID and CLIP score are the standard automatic quality checks.
- Check the licence of the base model and your rights to the training images before commercial use.
- Codiste is an AI agent development studio that builds custom generative AI systems for funded founders and CTOs.
How to Build a Generative AI Model for Image Synthesis: 7 Steps
1. Define what the model must produce
Write down the image type, style, size and daily volume. "Product photos of our shoes on plain backgrounds" leads to a different build than "concept art in our game's style".
2. Choose your path: API, fine-tune or train from scratch
- Use an image API when you need general images fast and have no special style.
- Fine-tune an open model, such as a Stable Diffusion version, when you need your own product, character or brand style. This is the usual choice.
- Train from scratch only for a new kind of image, such as medical scans, with millions of examples and a large budget.
3. Collect and prepare the training images
For fine-tuning, a few hundred to a few thousand clean, consistent images are typical. Remove duplicates, crop to the target size, write a short caption for each image, and record where every image came from and your right to use it.
4. Fine-tune or train
Fine-tuning methods such as LoRA and DreamBooth train a small set of extra weights on top of the base model, often on a single GPU. Training from scratch needs a cluster of GPUs for days or weeks. Open-source libraries such as Hugging Face Diffusers support both.
5. Measure quality
Use FID (Frechet Inception Distance) to compare generated images with real ones, and CLIP score to check how well images match their prompts. Then have people review a sample for errors, brand fit and safety.
6. Add safety controls
Filter prompts and outputs for unsafe content, and add a visible or invisible watermark where your market requires it.
7. Deploy and monitor
Serve the model behind an API on GPU servers, cache common requests, track cost per image and collect user feedback to improve the next version.
Building a different kind of AI model?
If you want to create an AI model for predictions or classification rather than images, the steps are similar: define the task, prepare data, choose a model, train, test and deploy. See our guide on how to build a machine learning model in 7 steps.
What is Generative AI?
Generative AI is a group of algorithms that can make new, believable examples from data they've observed. Rather than discerning models that only spot differences in data categories, creators' models make fresh content that looks a lot like real-life instances.
Generative AI, known for its skill in crafting diverse and top-tier content, has risen to fame in many fields. As per the research, it is shown that GenAI influence is growing, and we can see it through the rise in related articles, citations, and real-world uses.
Moreover, the power of generative models can be put into numbers. We use things like FID for picture creation. Studies tell us that the best of these models have low FID scores. This means they're good at making generated images look like real ones. Such number-based grading highlights generative AI's knack for mimicking complex data patterns.
Importance of Generative AI
GenAI is very important in the fields of artificial intelligence (AI) and machine learning (ML). Its importance can be emphasized with the following:
- Content Creation: Generative AI helps automate the content creation process, from image and video synthesis to text generation. Influences from this spread to areas like advertising, amusement, and artistry.
- Creative Expression: It assists in discovering fresh aspects of creative expression. Generative models are capable of unique image synthesis, designs, and other forms of creative content.
- Scientific Discovery: In areas such as biomedical research and drug development, image data augmentation in AI helps generate molecular structures and identify potential drug candidates.
Role of Generative AI
Generative AI changes more than just tech skills. It alters our approach to utilizing data and technological advancements. Some of its main roles are:
- Improve creativity : Generative AI improves human creativity by providing tools and models that inspire and support the creative process.
- Content generation automation: Generative models play a key role in automating content generation and reducing manual work for tasks such as image synthesis, text generation, etc.
- Contribution to research: In scientific research, generative AI facilitates the generation of synthetic data and assists researchers in tasks where access to real-world data may be limited or difficult.
Distinction between Generative and Discriminative Models
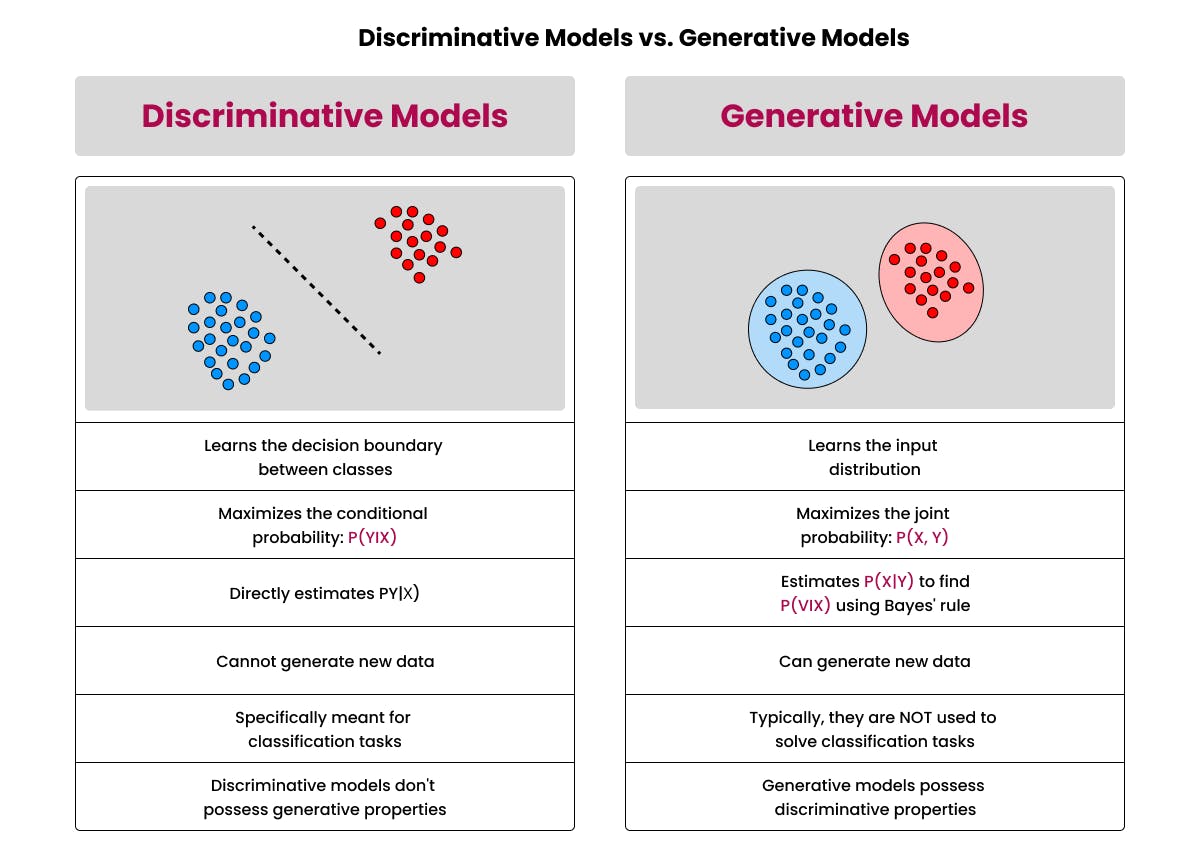
The main difference between generative and discriminative models is their goals:
- Generative models: These models are designed to generate new data samples that are very similar to existing data. You will learn basic patterns of data distribution and be able to create novel examples.
- Discriminant Model: In contrast, discriminant models focus on differentiating between different categories or classes in the data. They learn decision boundaries between classes and are often used in classification tasks.
Understanding this difference is critical to choosing the right model for a specific task. Generative models have many uses in creating new content, while discriminative models excel in classification tasks by distinguishing between predefined categories.
Let's explore the different types of generative models, focusing on Variational Autoencoders (VAEs), and Generative Adversarial Networks (GANs), and briefly touching upon other popular generative model architectures.
Types of Generative Models
Think of generative models as tools that create new sets of data. They mirror existing data trends. These models pick up on data patterns, allowing them to form fresh content. They learn what the data probably looks like, then use that to create new pieces.
What Are Diffusion Models?
A diffusion model learns to turn random noise into an image by removing the noise step by step, guided by a text prompt. Diffusion models are more stable to train than GANs and give more varied results, which is why they replaced GANs in most image generators after 2022.
What are Variational Autoencoders (VAEs)?
Variational Autoencoders, or VAEs, are a kind of model that makes new things. They use ideas from autoencoders and probabilistic graphical models. Important parts of VAEs are:
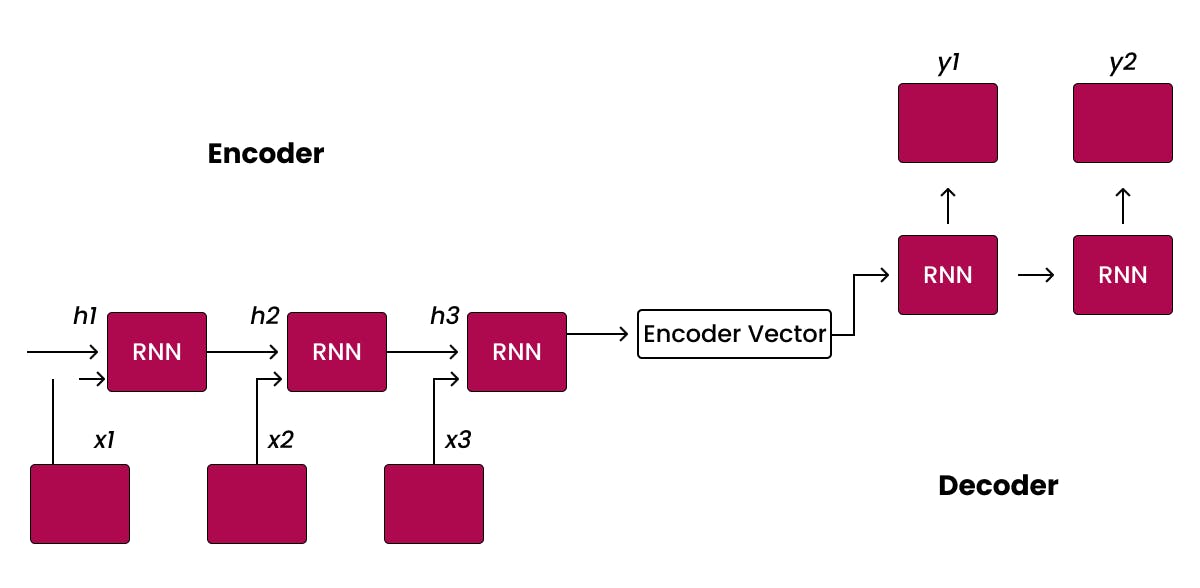
- Encoder
The encoder takes the input data and maps it to a probability distribution in a lower dimensional latent space. This distribution represents the uncertainty in the input data. - Latent Space
A latent space is a low-dimensional representation of the input data that captures essential features. It is characterised by mean and variance and allows the sampling of different data points. - Decoder
The decoder reconstructs the input data from sample points in the latent space. During training, the goal of VAE is to minimise the reconstruction loss and regulate the distribution of the latent space.
VAEs are particularly effective at capturing underlying data structures and are widely used in image synthesis, data compression, and generation tasks.
What are Generative Adversarial Networks (GANs)?
Generative adversarial networks (GAN) work according to the principle of adversarial training and include two neural networks - a generator and a discriminator.
- Generator
Generators create synthetic data samples by mapping random noise from latent space to data space. The goal is to generate real data that is indistinguishable from real examples. - Discriminator
The discriminator evaluates whether a given data sample is real (from the actual data set) or fake (generated by the generator). The goal of the discriminator is to correctly classify the source of the data. - Adversarial Training
GANs participate in a continuous game in which the generator and discriminator compete continuously. The generator improves its ability to generate real data by fooling the discriminator, while the discriminator improves its ability to distinguish between real and synthetic data.
GANs are extremely effective at generating photorealistic images, and their applications extend to image synthesis, AI models, style transfer, and creative content generation.
Other Popular Generative Model Architectures
While VAEs and GANs are at the forefront, other generative model architectures are gaining attention for specific applications. Two such architectures are:
1. Autoencoders
- Encoder-Decoder Structure: An autoencoder consists of an encoder network that compresses input data into a low-dimensional representation and a decoder network that reconstructs the original data from that representation.
- Applications: Autoencoders are used for tasks such as image reconstruction, noise reduction, and feature learning. They find applications in dimensionality reduction and data compression.
2. PixelCNN and PixelRNN
- Pixel-wise Generation:
PixelCNN and PixelRNN are models that focus on generating images pixel by pixel while taking into account dependencies between adjacent pixels. - Applications
These models have proven successful in generating high-resolution images and are used in tasks where capturing fine-grained details is critical. These models show the diversity of generative architectures, each with its advantages and applications in different domains. The selection of a generative model depends on the specific requirements of the task/project and factors such as data complexity, application goals, computing resources, and more.
How do Generative Models Work?
A prominent type of generative model, the Generative Adversarial Network (GAN), aims to create new data instances that look like a given training dataset. These models gain knowledge of the patterns and structures within the training data and use this to spawn realistic and innovative samples. Generative models, which encompass GANs, are a machine learning subset.
Introduced by Ian Goodfellow and associates in 2014, the components of Generative Adversarial Networks are the Discriminator and the Generator.
- Generator
To simulate training data, the generator technically creates synthetic data samples by beginning with random interference and gradually perfecting its result.
During the training process, the generator's output is scrutinized and compared to actual data, and the generator is then fine-tuned to minimize the incongruities between the two. - Discriminator
The discriminator acts as a binary classifier, distinguishing between real and generated data.
Training is done using real data samples generated by the generator.
As training proceeds, the discriminator can distinguish between real and synthetic data, providing valuable feedback to the generator.
Adversarial Training
The generator and discriminator participate in a competitive process called adversarial training:
- Training the Generator
Generators are designed to generate synthetic data that is indistinguishable from real data.
It continuously refines its output based on feedback from the discriminator.
The goal is to generate data that fools the discriminator into classifying it as real data. - Training the Discriminator
Discriminator learning improves the ability to distinguish between real and generated data.
It provides feedback to the generator, creating an improvement cycle for both components.
Convergence
Ideally, the GAN training process continues until the generator generates data that is nearly indistinguishable from real data, and the discriminator has difficulty distinguishing between the two. This state is called equilibrium or convergence.
Challenges and Refinements
Despite the power of GANs, challenges such as mode collapse (limited diversity produced by the generator) and training instability remain the same. Researchers are constantly improving GAN architectures and training strategies to solve these problems.
Applications and Extensions
Generative AI models, especially GANs, have made breakthroughs in image synthesis, style transfer, and more. Extensions such as conditional GANs can extend the applicability of generative models by generating targeted data based on specific input conditions.
Understanding how generative models work is fundamental to realizing their creative potential in fields ranging from art and design to scientific research. As advancements continue, the generative AI models are likely to expand, opening up new possibilities for artificial intelligence and creative computing.
Applications of Generative AI
Generative AI based on advanced machine learning techniques has found diverse applications in various fields, proving its versatility and transformative potential. The following are the main applications of generative AI:
- Image Generation and Manipulation
Generative models, especially Generative Adversarial Networks (GANs), are characterized by image generation and manipulation. Industries ranging from graphic design to entertainment make use of these models to create visually stunning and authentic images, whether they are created entirely from scratch using AI or manipulated from existing ones.
Example: DeepDream, a generative model developed by Google, transforms images by enhancing and modifying patterns within the image. - Text Generation and Language Modeling
Generative AI models are capable of producing human-like text and language modeling tasks. Natural language processing (NLP) models like OpenAI's GPT family can generate coherent and contextual text, which makes them valuable for content creation, chatbots, and automated writing tasks.
Example: OpenAI's GPT-3 has been employed for text generation in applications like chatbots, content creation, and even assisting in coding tasks by understanding and generating code snippets. - Creativity and Art Generation
Generative AI has ushered in a new era of creativity, enabling machines to autonomously generate art and creative content. Artists and designers use these models to explore new concepts, styles, and expressions that expand the horizons of traditional styles of creation.
Example: The creation of unique and visually stunning artworks using generative models like DALL-E, which generates images based on textual prompts. - Biomedical Research and Drug Discovery
Generative AI has made significant contributions to biomedical research and drug development by generating molecular structures, predicting interactions, and simulating biological processes. These models accelerate the identification of competent drug candidates and thus, help in reducing the time and resources needed for drug development.
Example: Generative models help scientists create molecular structures and forecast their traits. This is vital in the invention of new medicines and grasping intricate biosystems.
Yet, generative AI's capabilities stretch far beyond those uses. As the tech world progresses, generative AI is bound to become even more influential. It's changing how we tackle a variety of fields and obstacles.
Case Studies of Real-World Applications
AI programs that create images are helpful in many actual situations. Let's explore these benefits with some real-life examples:
- Style Transfer in Art and Design
Style transfer applies the look of one image, such as a famous painting, to another. Early services such as DeepArt made it popular, and design tools now offer similar features built on generative models. - Medical Imaging
The generative AI model plays a crucial role in the medical industry as image synthesis. Case studies help to show how it's used to make true-to-life medical pictures. They assist in training health workers and bettering diagnostic imaging. The full data set aids in teaching models to spot different illnesses. This helps enhance medical imaging tech.
Example: The use of generative models to create high-fidelity synthetic medical images for training radiologists, ensuring better diagnostic accuracy in real-world scenarios. - Video Game Design
Creating realistic textures, environments, and characters in the gaming industry is made possible thanks to the integral role of generative AI. Notably, real-life examples reveal how these models enhance gaming by making highly realistic scenes. This tech speeds up the challenging task of creating big virtual worlds. It lets game makers create large and captivating worlds.
Example: NVIDIA's GauGAN is a generative model that turns rough sketches into realistic landscapes in real-time. - Autonomous Vehicles
Self-driving teams use simulated and synthetic images to test how their systems handle rare road situations without waiting to meet them in real traffic. - Data Augmentation in Machine Learning
Generative models create extra training images, for example rare defects or unusual lighting, so other models learn from more varied data. - Content Creation in Entertainment
Generative AI is extensively used in the entertainment industry for content creation. Case studies reveal the role of these models in making special effects, crafted virtual worlds, and even whole scenes or characters, cutting down the human effort in the art-making process.
Example: Generative models help make lifelike special effects and CGI scenes for movies. These show how the world of entertainment content creation could be changed.
All these case studies together show how and why generative AI models are helpful in real life. They are used for picture creation in solving tricky problems and enhancing various sectors.
Challenges of Generative AI
The development and deployment of generative AI are hindered by several challenges that could affect its potential impact. Below are explanations of these obstacles that must be overcome:
- Training Instability
Often, complex generative models, such as GANs (Generative Adversarial Networks), struggle with training stability. One form of instability is mode collapse when the generator yields restricted output diversity. Alternatively, convergence can be challenging, resulting in prolonged training periods. To alleviate these concerns, scientists and professionals consistently devise reliable training tactics. - Ethical Concerns
Image data augmentation in AI can produce convincing but completely falsified images and videos has brought ethical issues to the forefront. Sharing false facts, making dishonest creations, and forging harmful media using generative models can hurt our privacy, security, and trust. We need to find a way to mix new tech ideas with good morals. It's a tough problem we still face in the industry. - Data Quality and Bias
The generative AI model relies a lot on training data. The quality of this data plays a huge role in the result. Sometimes, biases from the original data can accidentally seep into the AI results. This leads to skewed or unfair outcomes. Making sure the data sets are varied and accurate is important. Alongside this, finding ways to detect and settle bias issues are the main hurdles in developing AI that creates. - Computational Resources
Training state-of-the-art generative models requires significant computing resources, including powerful GPUs or TPUs and large amounts of memory. This is a challenge for smaller organisations or individual researchers who have access to such resources. Developing more resource-efficient AI models and training techniques is critical to making generative AI more accessible.
Limitations of Generative AI
Although generative AI is an innovative approach, it has its limitations. Understanding these limitations is critical for realistic expectations and responsible use:
- Uncertainty in Outputs
Generative models often struggle to provide reliable uncertainty estimates for their results. Knowing if a model can be trusted or if it's unsure is super important. This is extra true in situations where wrong guesses can cause real problems. Making the ability of these generative models to measure uncertainty better is something a lot of people are looking into. - Domain Specificity
Generative models are usually designed and trained for a specific domain or task. Transferring knowledge from one area to another can be challenging. A model trained on images may perform poorly when asked to generate text, and vice versa. Developing more general models that generalise to different datasets and tasks is a persistent limitation. - Interpretability
Generative models, especially deep neural networks, are often viewed as black-box systems, making their decision-making processes difficult to explain. Lack of interpretability is a problem, especially in critical applications such as healthcare. - Security Risks
Generative models are vulnerable to adversarial attacks, where carefully crafted inputs can trick the model into producing incorrect outputs. Understanding and mitigating these security risks is critical, especially in applications where the reliability and integrity of generated content are critical.
Future Trends and Developments
Generative AI has come a long way, but ongoing research and development continue to shape its future. Some trends and developments are expected to emerge in the coming years:
- Improve image synthesis
Future generative models are expected to produce more realistic, lifelike images. Advances in model architecture, training techniques, and the integration of additional modalities such as 3D structures will help bring AI image synthesis to new levels. - Improved control and customisation
The research focuses on increasing user control over generative models. This includes the ability to control the generation process with specific attributes, allowing for more personalized and customized output. Conditional generative models and user-guided training methods are likely to become more important. - Multimodal generation model
The integration of generative models across different modalities (e.g. combining text and image generation) is an area of increasing interest. Multimodal models enable a more complete understanding of data and lead to applications in storytelling, content creation, and problem-solving across multiple types of information. - Ethical considerations
As the use of generative AI becomes more widespread, addressing ethical issues and potential abuses are key areas of development. Researchers are exploring ways to ensure responsible use, prevent malicious applications such as deepfakes, and develop guidelines for the ethical development and deployment of artificial intelligence.
Summary: The Practical Path to Your Own Image Model
For most teams the practical path is: choose an open diffusion model, fine-tune it on your own images, measure it with FID, CLIP score and human review, and deploy it with safety filters. Train from scratch only when no existing model can learn your images.
Codiste is an AI agent development studio that builds custom generative AI systems for funded founders and CTOs. Talk to us about your image generation project.