
Artificial Intelligence
June 12, 2024

A generative adversarial network (GAN) is a generative AI model made of two neural networks trained against each other: a generator that creates fake samples, such as images, and a discriminator that tries to tell fake samples from real ones. As they compete, the generator learns to produce realistic new data.
Generative Adversarial Networks (GANs) are one of the key advances in deep learning. Since their introduction in 2014, they have become a widely studied area of machine learning, with striking results across many fields.
In simple terms, GANs generate new, synthetic data that closely matches the patterns of real training data. For example, train a GAN on thousands of portrait photos and it can produce new faces that look real but do not belong to any actual person.
This guide explains how GANs work, the main types of GANs, how they compare with diffusion models, and practical examples.
GANs consist of two competing neural network models:
The job of the Generator is to create synthetic data samples that are as close as possible to real data distribution, while the Discriminator tries to identify which samples are fake (created by the Generator) and which ones are real (from the actual training dataset).
Let's take the example of generating higher resolution celebrity photos from only low resolution input images. The Generator model starts with a random input vector called latent vector or latent space that is fed into the neural network to produce an output. Initially, this output would look gibberish but as training progresses, the Generator learns to transform this random noise into realistic synthetic images.
The Discriminator model receives a combination of real images from the actual celebrity photos dataset along with the images produced by Generator. It tries to classify them into real or fake categories. The Discriminator also improves continuously during training to better identify fake images.
Generator and Discriminator models are trained together in an adversarial setup where each one tries to outsmart the other. Through this back-and-forth competition, the Generator model keeps getting better at producing fake images that closely match underlying data distribution but aren't part of actual training samples.
This iterative adversarial training process reaches equilibrium when the Discriminator model is no longer able to differentiate between real data points and the synthesised fake data points produced by Generator. In a well trained GAN model, the synthetic outputs look astonishingly realistic and creative compared to other generative algorithms! Let us now explore details about each one of them.
The Generator and Discriminator models are the two competing neural networks that lie at the heart of all GAN architectures.
The Generator model is tasked with changing an input random noise vector into realistic synthesised data that matches the distribution of actual training data. For example, in the case of a GAN trained on celebrity photos dataset, the Generator would take as input a latent vector consisting of random values and try to map it to a lifelike synthetic human face image that could pass off as a real celebrity's photo.
The Generator is very similar to a conditional generative model with the output conditioned on the input noise vector. Architecturally, the Generator consists of an input layer that takes in the latent vector followed by a series of upsampling layers (transpose convolution layers in case of image data) and normalisation layers that eventually construct the high dimensional output representing synthesised data.
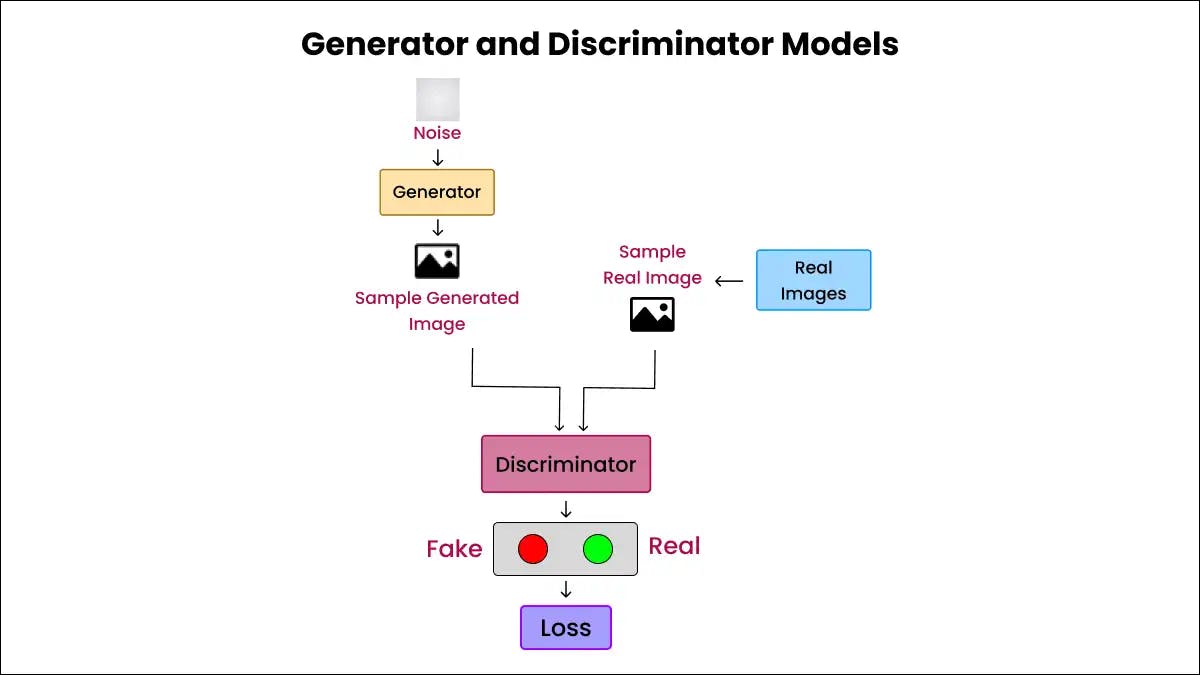
The discriminator's role during training is to give feedback to the generator: every time it spots a fake, that signal is used to improve the generator.
The discriminator is a binary classification model that tries to tell real data points (from the training dataset) from fake samples (produced by the generator). In the portrait example, it receives a mix of generated images and real photos and predicts which are real.
Structurally, the discriminator is a series of convolutional layers with normalisation and dropout layers, ending in a sigmoid output that gives a probability between 0 and 1 that the input is real.
During adversarial training, the generator tries to fool the discriminator into classifying fake data as real, while the discriminator tries to get better at spotting fakes. This feedback loop makes both models improve.
The most fascinating aspect of GANs is the adversarial training methodology that pits the two models against each other in a minimax optimization game.
The process starts with the Discriminator model being trained by using labelled real samples from training dataset as positive examples and fake samples produced by randomly initialised Generators as negative examples. The Discriminator learns to classify between these two classes by optimising its classification objective.
Next, the Generator model is trained by using unlabelled random noise samples as input while keeping the Discriminator model frozen. The target labels for all noise samples are set to 1 simulating the positive 'real data' class. Optimising its loss during backpropagation, the untrained Generator learns to better trick the Discriminator into classifying its outputs as belonging to real data distribution.
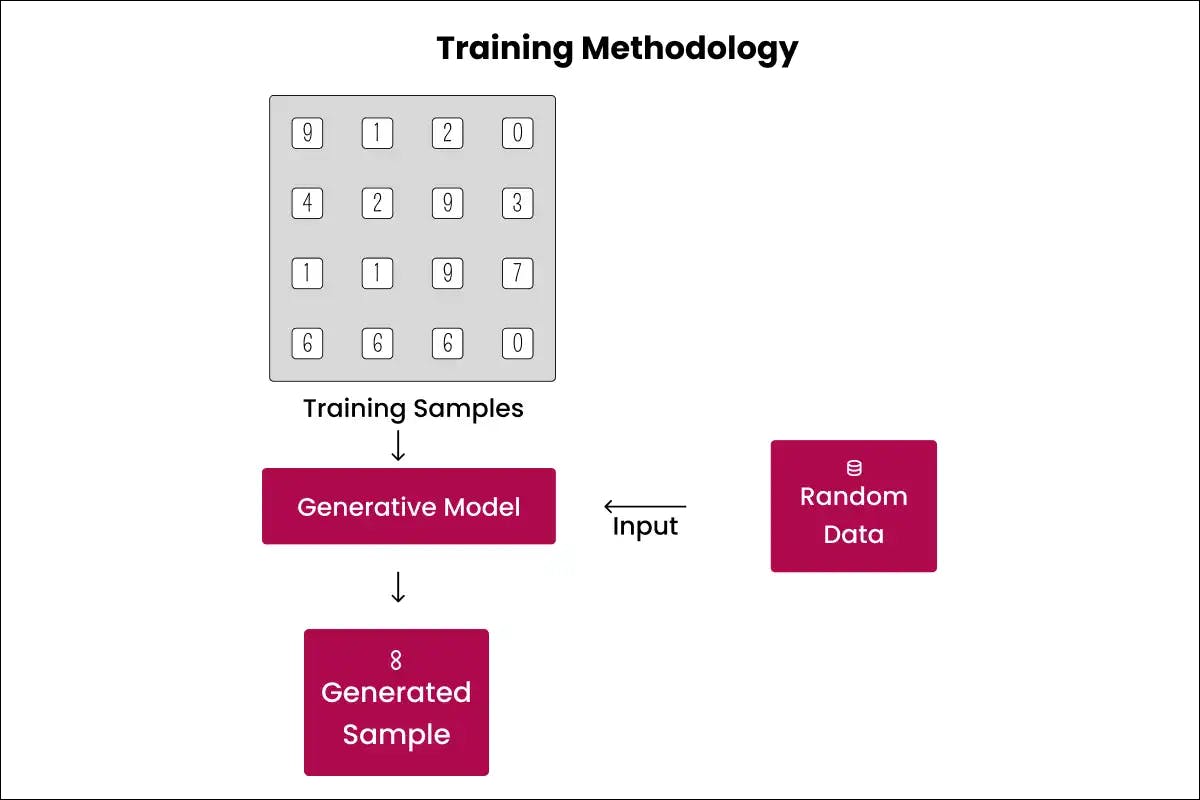
The Discriminator model is then retrained with the latest fake samples produced by the newly trained Generator combined with true samples from the dataset to improve its classification boundary.
This alternate, cyclic training methodology between the two networks in an adversarial setup accelerates learning for both models through competitive feedback. Over multiple rounds, the Generator gets better at creating realistic synthesised data while Discriminator evolves to be an almost perfect classifier between true and generated fake distributions.
The equilibrium is reached when the Discriminator model can no longer reliably differentiate between true samples and the Generator's fake outputs indicating the underlying distributions have aligned.
The most important aspect that makes GAN models truly unique is the adversarial relationship nurtured between the two networks through the training framework. This competitive rather than collaborative setup is crucial to enable generative capabilities for synthetic data generation.
Each model perceives the other as an adversary that tries to undermine it and hence is forced to continuously evolve through constant feedback and criticism. For the Generator, fooling the Discriminator model becomes the single objective driving all learnings. For the Discriminator, not getting swayed by the Generator's fake samples becomes pivotal.
This adversarial dynamic accelerates learning dramatically across both models as compared to fighting against a static non-evolving loss function which plateaus model performance after some time. Through rivalry, each model is made accountable to the other leading to an ever-improving generative system.
The min-max game framework formalises this adversarial interplay into a sound mathematical objective where the Generator tries to maximise the probability of the Discriminator making a mistake while the Discriminator tries to minimise it. This builds incentives for direct competition helping discover intricate data patterns that classical approaches struggle to replicate.
Researchers believe that the adversarial setup allows for an effective cooperation-adversarial duality that enhances creativity and leads to distributional alignment and stable convergence - key factors behind the success of GAN models and their ability to capture the richness and complexity of multidimensional distributions.
Since 2014, researchers have developed many GAN variations for more stable training, faster convergence and specialised uses. The best known are:
1. Deep Convolutional GAN (DCGAN)
Uses convolutional layers for both Generator & Discriminator models which helps in working with image data. Also introduces architectural constraints for stable training.
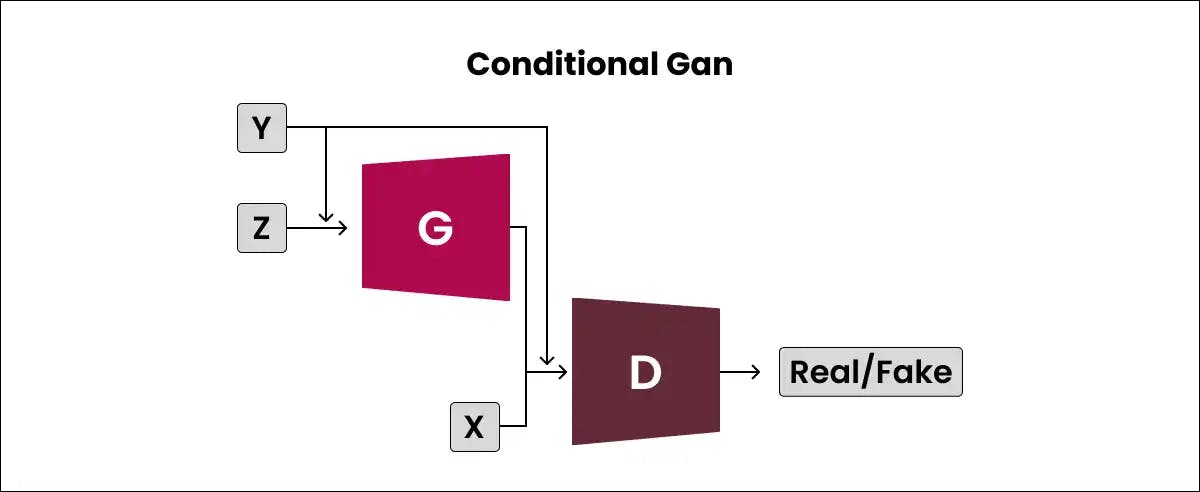
2. Conditional GAN (cGAN)
This makes the GAN model conditioned on additional information such as class labels or text descriptions. Enables control over the image synthesis process.
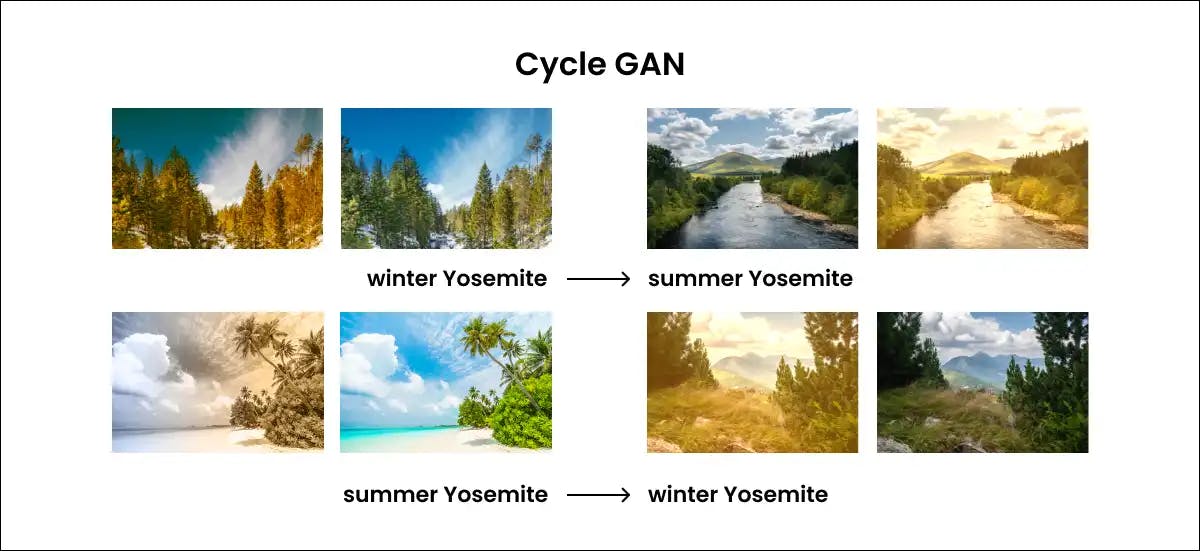
3. CycleGAN
Enables unpaired image-to-image translation between domains (for eg. horses to zebras; apples to oranges etc.) without the need for matched training data.
4. StyleGAN
Adds style transfer techniques into the Generator model along with improved training methodology resulting in high-resolution, photorealistic generated images. Sets new advances in face image generation.
5. BigGAN
BigGAN (DeepMind, 2018) scaled up GAN training with much larger models and batches, and introduced the truncation trick to trade variety for image quality.
6. SeqGAN
Applies GAN framework for generating sequential text data. Useful for tasks like dialogue systems, songwriting, etc. requiring contextual consistency.
7. InfoGAN
Makes unsupervised representation learning interpretable by maximising mutual information between a small subset of latent variables and outputs.
Research on GANs continues in areas such as healthcare, science and art.
A GAN creates an image in one fast step, but its adversarial training can be unstable and can collapse to a few similar outputs (mode collapse). A diffusion model learns to remove noise from an image step by step; it trains more stably and gives more varied results, but needs more steps to generate. That is why Stable Diffusion, DALL-E, Midjourney and Imagen use diffusion. GANs remain useful for real-time tasks such as super-resolution and video filters.
For a practical guide, see how to build a generative AI model for image synthesis.
GANs are used across many fields. Three well-known examples:
Other notable use cases are:
The list of uses keeps growing. Along with the possibilities, practitioners and builders are responsible for using GANs ethically.
Generative adversarial networks are undoubtedly one of the most promising advances in deep learning of the past decade. From creating photorealistic human faces to designing molecules with desired chemical attributes, GANs have delivered stunning performance across tasks and verticals at a breakneck pace! And compute infrastructure expansions led by players like Tesla foreshadow even bigger deployments soon.
However, like any technological milestone having deep societal impacts, conscious governance, and ethical considerations become pivotal so that innovations arbitrate for collective human progress. From the use of GAN generated media to lead public opinions astray to data privacy aspects of information implicitly captured in generative models - transparency and accountability will need to be safeguarded.
Researchers and corporations already have some initiatives around detecting GAN generated fake media, controlling information leakage from released models etc. However the continuous evolution of this technology mandates active, open participation and vigilance from all stakeholders involved so that innovative possibilities are weighed judiciously against intended and unintended societal impacts.
The path forward entails upholding principles of fairness and transparency while tackling difficult questions around access, consent, redressal, and governance of user data and derived generative models. Multi-disciplinary engagements spanning technology, arts, humanities, and social sciences will become crucial to help institute ethical norms and reflective oversight for generative AI systems before large-scale impacts come into effect.
This necessary self-regulation guided by ethics and values shall be pivotal for long term sustenance of technological innovations and inclusive human progress.
We must explore what's possible with generative modelling with this balanced outlook, but with wisdom that comes from open, mindful questioning and collective responsibility towards each other and our shared future.
GANs train a generator and a discriminator against each other to create realistic data. They changed image generation from 2014 to 2021 and are still used for fast tasks such as upscaling, while diffusion models now lead text-to-image generation.
Training, deploying and monitoring generative models well takes specialist knowledge, or models can produce biased or nonsensical outputs. Codiste is an AI agent development studio that builds custom generative AI systems for funded founders and CTOs. Talk to us about your generative AI project.
CTO & Co-Founder | Codiste
Nishant builds where ambitious ideas meet production reality. As CTO & Co-Founder at Codiste, he has helped ship 150+ AI systems. Through The CTO Story, he gets technical leaders talking about what rarely makes the slide deck: the trade-offs, failures, and decisions behind what actually ships.


Every great partnership begins with a conversation. Whether you're exploring possibilities or ready to scale, our team of specialists will help you navigate the journey.